Where Did the Saved Bytes Go? Compact Object Headers in IntelliJ IDEA
Summary
AI agents may make code faster to produce, but they don’t make it cheaper to run. In applications managing millions of objects, memory allocation and garbage collection still matter. The JVM has been addressing these costs on several fronts: ZGC targets garbage collection pauses, Project Leyden tackles startup and warmup, and Project Lilliput reduces the […]
Original Text
AI agents may make code faster to produce, but they don’t make it cheaper to run. In applications managing millions of objects, memory allocation and garbage collection still matter. The JVM has been addressing these costs on several fronts: ZGC targets garbage collection pauses, Project Leyden tackles startup and warmup, and Project Lilliput reduces the space occupied by every single object header. In Java 27, HotSpot enables compact object headers (Project Lilliput, JEP 534) by default.
Synthetic benchmarks frequently demonstrate smaller object footprints, but what does this change actually deliver for a massive, real-world JVM application? We evaluated the impact directly inside IntelliJ IDEA.
What are compact headers?
Every Java object carries a header. It identifies the object’s class and holds or encodes state used for locking, identity hashing, and garbage collection. Because every instance incurs this tax, shrinking the header represents an attractive target for memory optimization.
In the 64-bit HotSpot configuration we tested, a conventional instance header takes 12 bytes: an 8-byte mark word and a 4-byte class pointer. The compact layout compresses both into a single 8-byte word.
Does that translate to an immediate 10%–20% reduction in total application memory? Not necessarily. Below, we trace the impact of compact headers from raw object layouts and heap dumps through to resident process memory and interactive IDE workloads, highlighting where the savings materialize and where they vanish.
How we tested compact headers in IntelliJ IDEA
We measured three configurations with escalating resource demands:
No project (only the Welcome screen open).
Small project: Spring Petclinic, with about 3,370 Java/Kotlin lines of code.
Large project: IntelliJ IDEA monorepo, with about 26.5 million lines of code.
The codebase sizes differ by nearly four orders of magnitude, providing substantially different indexing profiles and memory footprints. For both project configurations, we ran an automated script that repeatedly opened Java source files, inserted and removed comments, resolved code references, saved changes, and closed the editor.
We used IntelliJ IDEA 2026.2.3 running on JBR 25.0.4 (the Java runtime used by JetBrains IDEs), explicitly switching compact headers on and off. Within each on/off comparison, the build, project snapshot, workload, and -Xmx values stayed the same. We ran multiple runs per configuration on an otherwise idle host, alternating the on/off execution order to minimize cache-warming and ordering bias.
Resident set size (RSS)
Let’s start with the primary metric users tend to notice when a process looks large: its RSS (resident set size).
RSS counts the physical RAM pages mapped to a process. This includes private memory pages and shared memory pages, such as dynamic libraries. Because shared pages count toward every process mapping them, RSS does not represent the amount of RAM exclusively held by the IDE.
We sampled the main IDE process using the ps command. The table below lists the mean of three per-run phase medians in MiB, with the lowest and highest run medians given in brackets.
Condition
Headers off, MiB
Headers on, MiB
Delta
Welcome screen
(-Xmx2048m)
1,226.9 [1,213.6–1,247.8]
1,266.4 [1,238.8–1,294.1]
+39.5 MiB (+3.22%)
Petclinic active
(-Xmx2048m)
3,576.4 [3,442.8–3,647.1]
3,531.7 [3,436.3–3,625.3]
−44.7 MiB (−1.25%)
Monorepo active
(-Xmx4096m)
7,352.6 [7,351.3–7,353.4]
7,376.9 [7,339.8–7,426.1]
+24.3 MiB (+0.33%)
Verdict: At identical -Xmx limits, compact headers produced no statistically significant or consistent reduction in overall RSS.
Does this imply that compact headers yielded no practical benefit? To answer that, we need to look inside the heap and find out how compact headers actually work, rather than assuming an across-the-board drop in process memory.
Measuring object footprints
Process RSS encompasses much more than live Java heap objects. Resident pages can include unallocated headroom inside the committed heap, class metadata, JIT-compiled code, thread stacks, native buffers and JVM data structures, shared libraries, and other memory-mapped files. Reducing object headers alone, therefore, might not necessarily lower the process’s RSS by a matching number of bytes (if it makes a visible change at all).
To isolate the structural savings, we compared the object footprint – how many bytes the same set of captured objects would occupy under each header layout model.
For your projects, you can explore this directly in IntelliJ IDEA. Its memory dump shows instance counts, shallow sizes, and retained sizes by class, so you can see what occupies the heap. As of the 2026.3 EAP, it also offers compact-header-aware estimates using JOL’s layout models.
The table below contrasts the modeled footprints for identical captured heaps.
Captured population
Instances
Conventional model
Compact model
Memory saved
Welcome screen
2,587,924
141.533 MiB
132.619 MiB
8.914 MiB (6.3%)
Petclinic, headers off
9,335,990
472.304 MiB
442.633 MiB
29.671 MiB (6.3%)
Petclinic, headers on
9,314,900
470.790 MiB
441.179 MiB
29.610 MiB (6.3%)
Monorepo, headers off
19,102,676
924.818 MiB
848.823 MiB
75.995 MiB (8.2%)
Monorepo, headers on
19,980,536
953.401 MiB
873.060 MiB
80.341 MiB (8.4%)
Here, the savings are visible: The fixed-population model reduces the Welcome and Petclinic objects by about 6.3%, and the monorepo objects by 8.2%–8.4%. While system-level RSS obscured the effect, the memory savings within the heap are real.
Why the win is not fixed
Why doesn’t removing 4 bytes from the header translate to a uniform 4-byte saving for every single object? Because two heaps of the same size can contain very different objects, and the header is only one of the variables at play.
An instance also stores primitive fields and references. An array stores its length and element data. Their number, type, and reference width all affect an object’s overall size. In our comparison, field types and reference width stay the same, but changing the header can move field offsets and alter padding. Here’s how that works:
HotSpot rounds each object’s shallow size up to a multiple of eight bytes by default. That can absorb the four-byte header reduction: An object with one int stays 16 bytes in either layout (12 + 4 bytes, or 8 + 4 bytes plus 4 bytes of padding). An empty Object, by contrast, shrinks from 16 to 8 bytes; one with two int fields shrinks from 24 to 16 bytes, as illustrated in the image below:
There can also be padding inside an object. Fields have their own alignment requirements; they do not all start on eight-byte boundaries. In the HotSpot layout modeled here, ordinary field offsets follow their storage width: one byte for byte/boolean, two for short/char, four for int/float and compressed references, and eight for long/double. That is separate from rounding the whole object to an eight-byte size, and it is not a Java-language guarantee.
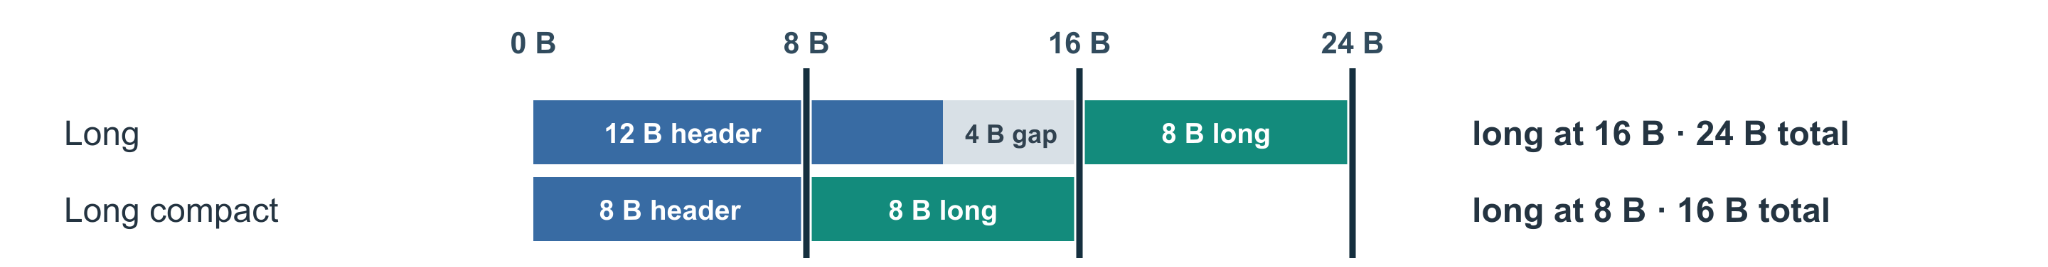
Let’s look at Long.value. After a 12-byte header, its eight-byte field starts at offset 16, leaving a four-byte gap. After an eight-byte header, it can start at offset 8. The whole object shrinks from 24 to 16 bytes. HotSpot can pack or reorder fields, so the exact offsets still depend on the class and the JVM’s layout rules.
Arrays show the same pattern: byte[0] stays 16 bytes, while byte[1] shrinks from 24 to 16 bytes. When a heap contains millions of different shapes, its total saving depends on that mix, not just the object count.
We checked these examples against actual shallow sizes with Instrumentation.getObjectSize on the same JBR, with compact headers explicitly off and on. A shallow size counts the object’s header, fields, and padding, but not any objects reached through its references. We also verified compressed references and alignment. Here is what JBR 25.0.4 reported:
Shape
Headers off
Headers on
Saved
Empty Object
16 B
8 B
One int field
16 B
0 B
Two int fields
24 B
16 B
8 B
Integer
16 B
0 B
Long
24 B
16 B
8 B
Node shape: int + three references
32 B
24 B
8 B
byte[0]
16 B
0 B
byte[1]
24 B
16 B
8 B
byte[4]
24 B
16 B
8 B
byte[8]
24 B
0 B
int[4]
32 B
0 B
Object[1000]
4,016 B
0 B
The takeaway from the table is simple: A smaller header does not make every object smaller. Total heap reduction depends entirely on an application’s object population profile.
Practical wins: Allocation, GC, and throughput
Even if the process’s RSS does not decline at a fixed -Xmx, does reduced object size benefit the runtime elsewhere? We looked for four effects:
Does the same workflow allocate fewer total megabytes?
Does the garbage collector run less often or consume fewer cycles?
Do scripted IDE operations become faster as the result of the changes above or effects like better CPU cache locality?
Can the application execute reliably under a smaller -Xmx?
For the first three questions, we compared headers off and on at the same -Xmx: 2,048 MiB for Petclinic and 4,096 MiB for the monorepo.
Did JVM allocate fewer bytes?
For each project, our benchmark script repeated the same sequence of operations: opening a Java file, inserting and removing a comment, resolving references, saving, and closing the editor. That includes concurrent background and probe work, so it is not an allocation summary for the edits in isolation.
If you want to analyze allocation hotspots in your own code, IntelliJ IDEA’s Memory Allocations profiler tracks call paths and timelines. Like IntelliJ IDEA’s heap dump tool, it natively models compact object headers, so you can expect true numbers for your application, regardless of your target JVM version.
Project
Scripted operations
Headers off, MiB
Headers on, MiB
Total reduction
Petclinic
75
671.2 [655.4–683.1]
612.3 [605.4–621.0]
−58.9 MiB (−8.8%)
Monorepo
384
5,241.6 [5,118.0–5,341.3]
4,558.2 [4,486.8–4,598.7]
−683.4 MiB (−13.0%)
Under identical workloads, compact headers eliminated 8.8% to 13.0% of total allocated volume.
Did the garbage collector have less to do?
Lower allocation volume could mean less work for the garbage collector. We compared the JVM’s GC counts and elapsed collection time during project opening/indexing, followed by GC pause times during scripted operations.
Project and phase
Metric
Headers off
Headers on
Delta
Petclinic, opening/indexing
GC events
90.7 [82–98]
82.3 [63–95]
−8.4 events (−9.3%)
Petclinic, opening/indexing
GC elapsed, ms
758.3 [733–788]
698.0 [595–783]
−60.3 ms (−8.0%)
Petclinic, opening/indexing
Recorded GC CPU, s
5.9 [5.6–6.1]
5.3 [4.8–5.9]
−0.6 s (−10.2%)
Petclinic, scripted operations
GC elapsed, ms
24.3 [10–50]
13.0 [0–25]
−11.3 ms (−46.5%)
Monorepo, opening/indexing
GC events
560.0 [546–574]
530.7 [527–534]
29.3 events (−5.2%)
Monorepo, opening/indexing
GC elapsed, ms
11,322 [10,944–11,823]
11,001 [10,965–11,061]
321 ms (−2.8%)
Monorepo, opening/indexing
Recorded GC CPU, s
88.9 [86.5–92.0]
85.7 [85.3–85.9]
−3.2 s (−3.6%)
Monorepo, scripted operations
GC elapsed, ms
92.0 [77–107]
72.0 [36–106]
−20.0 ms (−21.7%)
During monorepo opening/indexing, every compact-header run recorded fewer GC events than the conventional-header runs. Mean GC elapsed time and recorded GC CPU were lower in these comparisons, too.
Did IDE work speed up?
This is ultimately the question developers care about most. For the same operations, we compared their total time, their 95th-percentile operation latency, and process-wide CPU utilization.
Project
Metric
Headers off
Headers on
Delta
Petclinic
Cumulative operation time, s
3.682 [3.632–3.710]
3.568 [3.423–3.775]
−0.114 s (−3.1%)
Petclinic
Per-operation p95, ms
60.63 [59.51–61.72]
59.11 [52.81–63.48]
−1.52 ms (−2.5%)
Petclinic
Total process CPU, s
12.92 [12.66–13.18]
12.90 [12.62–13.09]
−0.02 s (−0.2%)
Monorepo
Cumulative operation time, s
16.768 [16.220–17.246]
16.751 [15.565–17.422]
−0.017 s (−0.1%)
Monorepo
Per-operation p95, ms
69.06 [68.56–69.44]
67.46 [64.48–69.53]
−1.60 ms (−2.3%)
Monorepo
Total process CPU, s
52.73 [51.95–53.24]
51.55 [49.58–52.84]
−1.18 s (−2.2%)
The performance numbers trend slightly positive, suggesting a modest speedup.
How low can -Xmx go?
If compact headers pack more instances into the same heap volume, how far can we drop -Xmx before workloads fail?
We stepped -Xmx downward until the indexing and editor scenarios could not completely reliably. A pass meant that the short scenario finished, even if it became slow.
The table below shows the lowest tested settings that completed every repeat for each project and header layout.
Project
Headers
Effective -Xmx, MiB
Active RSS, MiB
Opening/indexing, s
Opening/indexing GC, s
Fixed-work time, s
Petclinic
Compact
376
2,528.2 [2,465.4–2,558.2]
67.0 [60.0–71.0]
29.6 [22.9–32.6]
4.74 [4.42–5.09]
Petclinic
Conventional
400
2,529.3 [2,508.9–2,580.7]
69.5 [64.0–70.0]
31.9 [25.6–33.3]
5.18 [4.75–6.76]
Monorepo
Compact
1568
4,718.8 [4,658.6–4,837.0]
344.0 [344.0–348.0]
36.5 [36.4–39.6]
17.8 [17.8–17.8]
Monorepo
Conventional
1888
5,063.1 [4,804.2–5,097.9]
341.0 [338.0–344.0]
27.9 [27.8–33.5]
16.3 [16.2–17.4]
Note: These represent the boundary thresholds where test workloads consistently completed – not suggested production configurations.
For Petclinic, compact headers allowed us to lower the minimum viable heap from 400 MiB to 376 MiB (a 6% reduction). For the monorepo, the minimum ceiling dropped from 1,888 MiB down to 1,568 MiB – a 320 MiB (17%) saving.
Conclusion
Upgrades that make existing applications more efficient without requiring a single line of application code are rare. Compact object headers achieve this by reducing a memory tax paid by millions of objects. Alongside improvements to startup and garbage collection, they are part of Java’s broader work on runtime efficiency – strengthening the JVM at a time when we’re generating more code than ever.
When you adopt compact headers in your own applications, the actual benefit will depend on your mix of objects and their alignment. Many objects will take up less space, which often translates into lower allocation churn, reduced GC pressure, and a smaller viable heap ceiling. However, it does not guarantee an immediate, matching drop in process RSS or faster execution across the board. Measure those metrics separately, and don’t lower your -Xmx just because headers are supposed to be smaller.
You may already be using the feature in IntelliJ IDEA. The IntelliJ Platform change arrived in 2026.2, and Java 27 enables company headers by default. That removes any manual configuration as soon as you migrate to the new Java version – which is well worth doing, given how much runtime work has landed recently.
What would you like us to explore next? Are you interested in more articles on Java performance, newer Java features, or both? Let us know in the comments!
Lotu Radar provides attributed news summaries and links to the original publisher. Full reporting and copyright remain with the source.